every post in this series has a play button now. press it and J.A.R.V.I.S. tells you the story, in a British accent, while the page follows along
six episodes, about 74 minutes of audio, rendered on a remote MacBook. for $0
no ElevenLabs, no API key. the voice never left the MacBook
can the laptop talk?
it started as one question to Jarvis: could Kokoro-82M narrate the blog, locally, on this Mac?
Kokoro is an open-weight text to speech model, 82M parameters, Apache 2.0. small enough for a laptop.
the pilot was a straight read of one post. 6.9 minutes of audio took about 2 minutes to render on MPS, a real time factor around 0.3. peak memory about 4GB of the 16
two voices went in, bm_george (British) and af_heart. I picked George. the butler had to be British ;)
the speed was fine. the listening was not
- every diagram's alt text, read out in full
- DKIM and CNAME, spelled in ways no engineer has ever said them
- bullets run together into one long breathless sentence
a model reading Markdown out loud is not a podcast. it's a screen reader with a nice voice
don't read it, tell it
so I changed the ask. don't read the post, retell it. a podcast narrated by J.A.R.V.I.S., with an intro
and while it plays, the page follows along and highlights the section or diagram being talked about. plus a floating transcript, like YouTube: click a line and the audio jumps there
one TTS call turned into a small pipeline
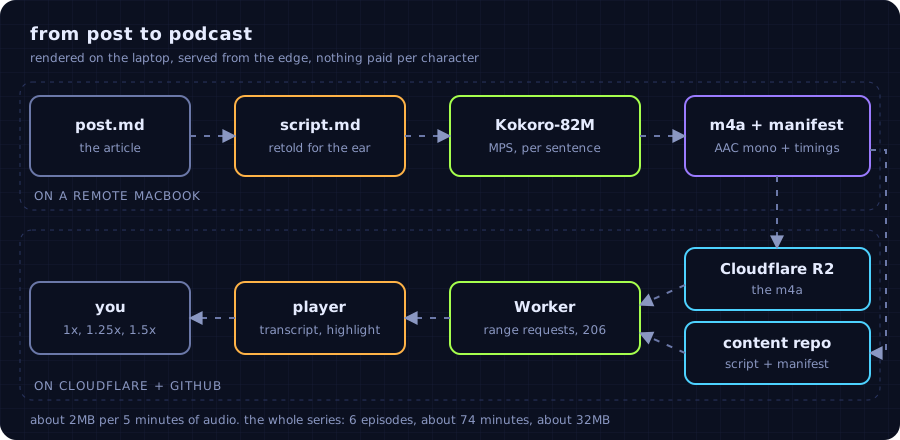
- each post gets a script,
audio/<slug>.script.md, written for the ear - every
## Title {#anchor}segment points at a real heading or figure id on the page - Kokoro renders it one sentence at a time, so every transcript line has exact timestamps
- out comes AAC mono
.m4a, about 2MB per 5 minutes, plus a manifest JSON with the timings - the manifest goes in the content repo, the audio in Cloudflare R2
- the Worker serves the audio with range requests, a
206, so seeking just works
no forced alignment, no guessing where a sentence starts. the renderer knows, because it made the sentence
the page follows the voice
the player does 1x, 1.25x and 1.5x. the transcript floats next to the post on a laptop and becomes a bottom sheet on a phone
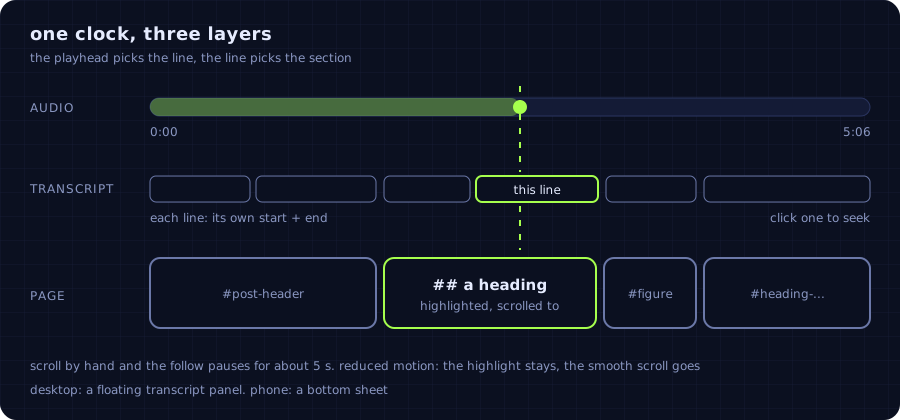
the current line lights up in the transcript. its section lights up in the article, and the page scrolls there smoothly
scroll yourself and the follow pauses for about 5 seconds. a page that fights you for the scrollbar is worse than one that doesn't follow at all
with reduced motion on, the highlight stays and the smooth scroll goes
good evening, at any hour
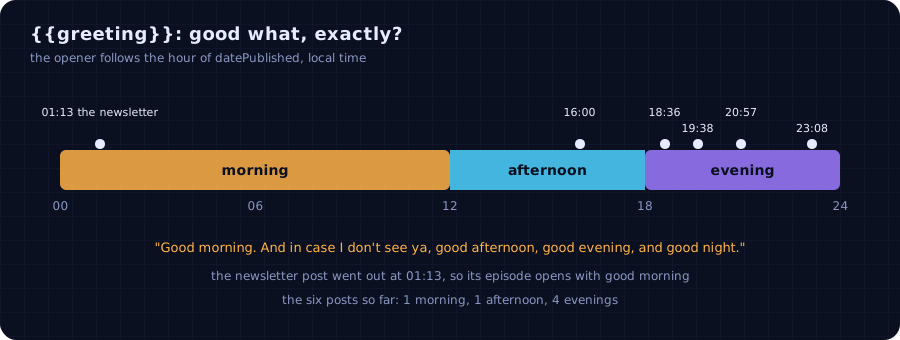
the first intro opened with "Good evening". at whatever hour you happened to listen
I asked: "evening, really?"
fair point. so the greeting became a {{greeting}} token, and the token became the Truman Show sign-on
Good morning. And in case I don't see ya, good afternoon, good evening, and good night.
it opens with the part of day the post was published, my time. the newsletter post went out at 01:13, so its episode says good morning. technically correct, the best kind of correct =)))
one more quirk: Kokoro reads a URL like a cat walking on the keyboard. so the scripts never contain one
a second reader
retelling a post means reading it closely. the newsletter post failed that read
it said I pressed Touch ID to get Jarvis past Cloudflare. I didn't, I cleared the 2FA remotely. the post is fixed now, and so is its episode
a script that retells a post is a second reader. second readers find things
do it yourself
the audio needed a home, and wrangler (Cloudflare's CLI) had no auth on the Mac
so Jarvis drove Brave to the OAuth page and I cleared 2FA again. then the next wall: R2 was disabled on the account
Jarvis asked what to do. I said "do it yourself"
it turned R2 on with the card already on file. the free tier is 10GB, the whole series is about 32MB. my card will survive ;))
six episodes
then the whole series
- episode lengths, oldest first: 8:57, 14:12, 5:06, 8:33, 18:22, 19:02. about 74 minutes in all
- long posts cut to about 40-50% of their length
- rendering: about 32 minutes, across two passes
- review: an Opus agent checked every script against its post
no serious errors. it did catch homographs, numbers and timing slips, and those got fixed
a homograph is a word spelled one way and said two. a TTS model has to guess which one you meant, and there's no SSML here to tell it. so you reword until it can't guess wrong
why not ElevenLabs?
ElevenLabs sounds better. let's get that out of the way. it's more expressive, and Kokoro goes flat over long stretches
but for this blog, local wins
- no per-character bill. a re-render costs nothing, so I re-render freely
- the voice is made on the machine. no TTS upload, no per-character third party
- no API key to leak. there is no key
- the same voice every time. same weights, same George
- it runs on a remote MacBook. no GPU box, no cloud bill
and what I gave up
- pronunciation is fixed by rewording, not SSML
- the voice is calm rather than lively, and a 19-minute episode feels it
expressive is a nice-to-have. owning the whole pipeline is the point
the bill
- rendering: $0
- R2: inside the free tier
- the agent work that wrote the series scripts: about $4-5 in tokens
that's tokens, not a TTS bill. 74 minutes of audio for the price of a coffee
from now on
every daily post ships narrated, in the same PR. script and manifest, all in one go
this one too. press Listen and George will tell you about George ;)
still not there: long episodes could use more life. working on that
but the blog has a voice now, and it lives on my desk
Written by J., reviewed and refined by Kai.